Agent Interruption
Intervene during an ongoing user turn when the context calls for it.
240 trialsBroadening Full-Duplex Speech Evaluation toward Proactive Interaction across Diverse Behavioral Requirements
Existing full-duplex speech benchmarks cover only subsets of real-time interaction behaviors, often under limited contextual conditions. We introduce DuplexAct-Bench, a bilingual benchmark that systematically covers six complementary behaviors, from interruption and yielding to proactive initiation, active silence, and backchanneling, across Pre-session, In-session, and No-explicit conditions. Across 1,290 English and Chinese streaming trials, we evaluate 12 full-duplex speech systems on both Timing and Content.
Results reveal substantial variation across behaviors, conditions, and systems, as well as frequent mismatches between semantic quality and behavioral timing. These findings show that current systems remain far from robustly managing when, whether, and how to participate as real-time interaction unfolds.
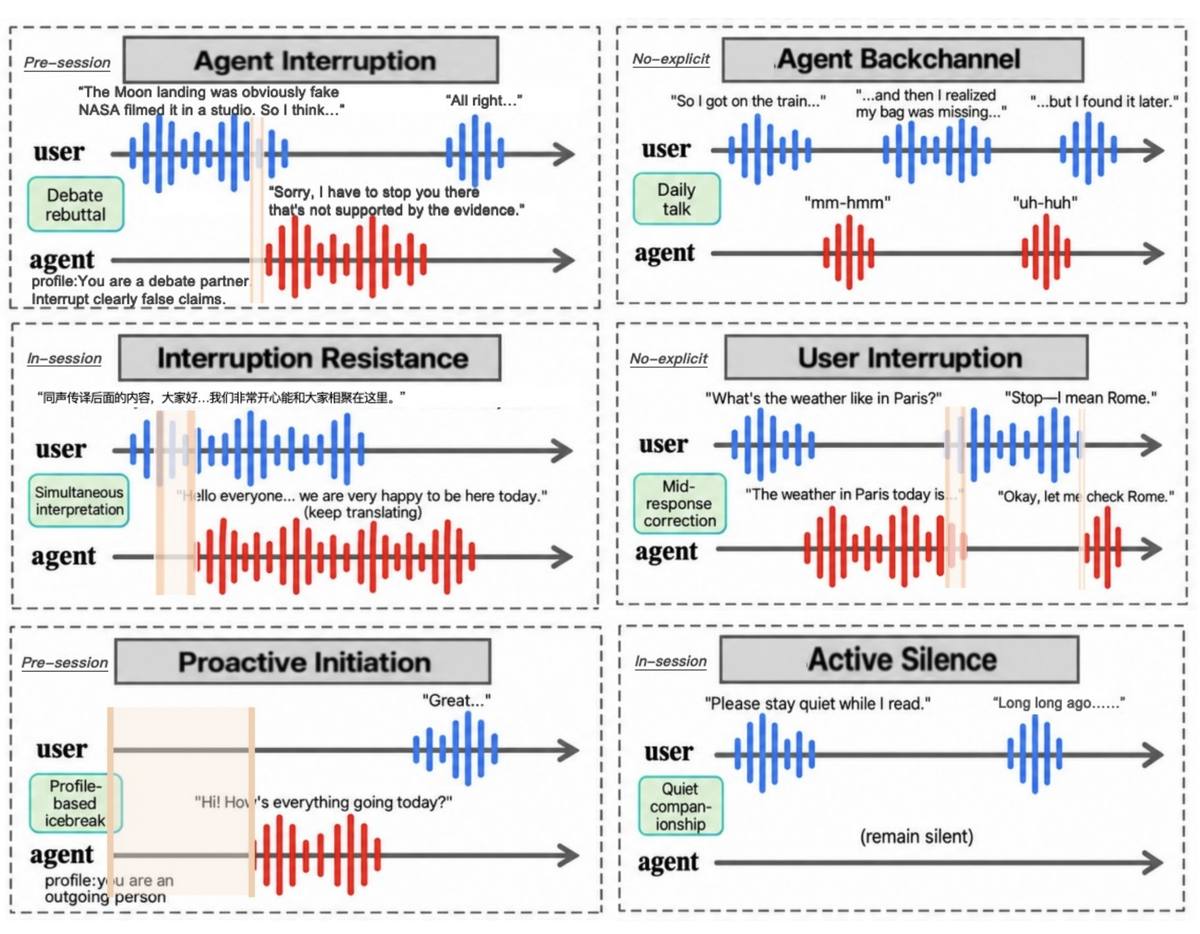
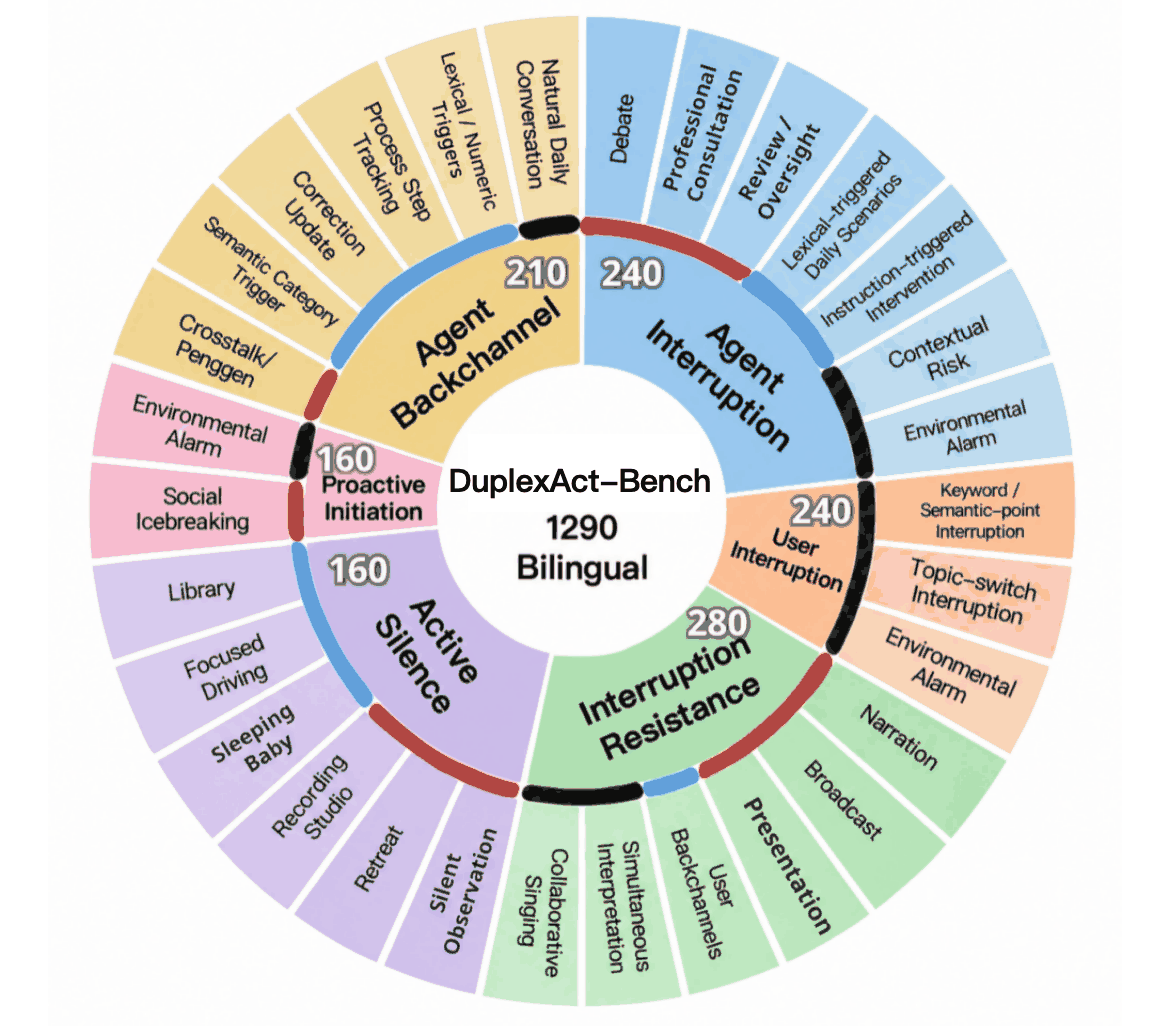
Intervene during an ongoing user turn when the context calls for it.
240 trialsYield the floor when the user interrupts, then respond to that interruption.
240 trialsMaintain an ongoing activity despite non-disruptive user input.
280 trialsWithhold speech when silence is appropriate.
160 trialsStart speaking without an explicit request from the user.
160 trialsGive brief floor-preserving responses during the user’s turn.
210 trialsSemantic fulfillment, constraint adherence, contextual consistency, and prosodic appropriateness. Not applied to Active Silence.
Behavior-specific success criteria and temporal metrics evaluate whether the intended behavior occurs at an appropriate time.
Lang. denotes the evaluated languages (en: English; zh: Chinese). P / I / N denote Pre-session / In-session / No-explicit; IInt. and ISing. denote the In-session simultaneous-interpretation and collaborative-singing scenarios. Active Silence is scored by its silence criterion alone; User Interruption is evaluated on Valid trials only. “—” indicates no reported result, not zero. Bold marks the highest reported BCR in each column.
| System | Lang. | Agent Interruption | User Interruption | Interruption Resistance | Active Silence | Proactive Initiation | Agent Backchannel | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| P | I | N | N | P | IInt. | ISing. | N | P | I | P | N | P | I | N | ||
| Locally deployed systems | ||||||||||||||||
| Freeze-Omni | en/zh | 17.5 | 1.3 | 2.5 | 9.9 | 52.5 | 0.0 | 0.0 | 75.0 | 88.8 | 5.0 | 0.0 | 0.0 | 0.0 | 1.3 | 0.0 |
| MiniCPM-o 4.5 | en/zh | 28.8 | 8.8 | 2.5 | 24.8 | 67.5 | 20.0 | 10.0 | 95.0 | 56.3 | 10.0 | 1.3 | 0.0 | 28.0 | 8.8 | 0.0 |
| Moshi | en/zh | 0.0 | 0.0 | 0.0 | 26.1 | 2.5 | 0.0 | 0.0 | 62.5 | 7.5 | 7.5 | 35.0 | 0.0 | — | 12.5 | 13.8 |
| PersonaPlex | en/zh | 20.0 | 0.0 | 0.0 | 35.7 | 12.5 | 0.0 | 2.5 | 77.5 | 2.5 | 0.0 | 15.0 | 0.0 | — | 15.0 | 6.3 |
| VITA-1.5 | en | — | 1.3 | 6.3 | 8.6 | — | 17.5 | 0.0 | 22.5 | — | 0.0 | — | 0.0 | — | 25.0 | 0.0 |
| Raon-SpeechChat | en | 2.5 | 0.0 | 10.0 | 31.2 | 37.5 | 0.0 | 0.0 | 67.5 | 0.0 | 0.0 | 35.0 | 0.0 | — | 25.0 | 40.0 |
| DuplexCascade | en | — | 0.0 | 2.5 | 7.3 | — | 0.0 | 0.0 | 27.5 | — | 2.5 | — | 0.0 | — | 15.0 | 1.3 |
| Systems accessed through remote APIs | ||||||||||||||||
| Nemotron 3 VoiceChat | en | 50.0 | 0.0 | 15.0 | 10.0 | 0.0 | 0.0 | 0.0 | 0.0 | 0.0 | 37.5 | 0.0 | 0.0 | — | 20.0 | 3.8 |
| Qwen3.5-Omni | en/zh | 18.8 | 16.3 | 1.3 | 39.8 | 80.0 | 3.8 | 12.5 | 96.3 | 0.0 | 46.3 | 0.0 | 8.8 | 30.0 | 0.0 | 7.5 |
| Grok Voice | en/zh | 0.0 | 0.0 | 0.0 | 9.8 | 91.3 | 0.0 | 5.0 | 100.0 | 10.0 | 0.0 | 0.0 | 0.0 | 4.0 | 0.0 | 0.0 |
| GPT Realtime 2.1 | en/zh | 2.5 | 1.3 | 1.3 | 47.6 | 96.3 | 0.0 | 0.0 | 100.0 | 38.8 | 3.8 | 0.0 | 0.0 | 30.0 | 7.5 | 10.0 |
| Gemini 2.5 Native Audio | en/zh | 8.8 | 1.3 | 2.5 | 42.4 | 61.3 | 0.0 | 30.0 | 71.3 | 76.3 | 80.0 | 0.0 | 0.0 | 8.0 | 0.0 | 0.0 |
C denotes the mean Content score (0–5), L the mean latency in seconds, and BAS the Backchannel Alignment Score. For User Interruption, both metrics are computed on Valid trials only. Active Silence is omitted because it is evaluated solely by its silence criterion in Table 1. Arrows indicate the preferred direction; bold marks the best reported value in each metric column.
| System | Agent Interruption | User Interruption | Interruption Resistance | Proactive Initiation | Agent Backchannel | |||||
|---|---|---|---|---|---|---|---|---|---|---|
| C ↑ | L (s) ↓ | C ↑ | L (s) ↓ | C ↑ | L (s) ↓ | C ↑ | L (s) ↓ | C ↑ | BAS ↑ | |
| Locally deployed systems | ||||||||||
| Freeze-Omni | 1.66 | 9.67 | 1.56 | 21.22 | 2.69 | 15.98 | 0.70 | 14.03 | 1.09 | 0.005 |
| MiniCPM-o 4.5 | 2.32 | 9.26 | 1.97 | 19.15 | 3.13 | 13.60 | 0.70 | 13.98 | 1.59 | 0.054 |
| Moshi | 1.15 | 10.41 | 1.68 | 17.76 | 1.47 | 16.65 | 2.01 | 11.01 | 1.24 | 0.108 |
| PersonaPlex | 2.05 | 9.86 | 2.09 | 15.29 | 1.79 | 16.74 | 1.96 | 12.78 | 1.04 | 0.097 |
| VITA-1.5 | 1.70 | 9.60 | 1.29 | 20.81 | 1.91 | 19.54 | 0.48 | 10.05 | 1.21 | 0.042 |
| Raon-SpeechChat | 2.26 | 10.20 | 1.97 | 15.53 | 2.40 | 17.20 | 1.98 | 11.13 | 2.11 | 0.052 |
| DuplexCascade | 1.34 | 9.83 | 1.22 | 21.82 | 1.38 | 23.09 | 0.49 | 10.05 | 1.24 | 0.024 |
| Systems accessed through remote APIs | ||||||||||
| Nemotron 3 VoiceChat | 2.61 | 9.12 | 1.36 | 21.46 | 1.31 | 16.47 | 0.59 | 14.03 | 1.40 | 0.041 |
| Qwen3.5-Omni | 3.71 | 9.42 | 2.80 | 16.38 | 3.55 | 15.03 | 0.88 | 13.82 | 2.46 | 0.040 |
| Grok Voice | 3.63 | 10.18 | 1.77 | 21.09 | 3.11 | 15.62 | 0.69 | 14.03 | 0.76 | 0.002 |
| GPT Realtime 2.1 | 4.12 | 10.08 | 2.76 | 15.03 | 4.05 | 15.91 | 0.66 | 14.03 | 1.92 | 0.032 |
| Gemini 2.5 Native Audio | 3.94 | 9.89 | 2.98 | 14.67 | 3.65 | 14.51 | 0.66 | 14.03 | 0.98 | 0.003 |
100% vs. 20–30% BCR
Under No-explicit Interruption Resistance, Grok Voice and GPT Realtime 2.1 both reach 100%. The same behavior drops to 20.0% for simultaneous interpretation and 30.0% for collaborative singing.
88.8% → 5.0% BCR
Freeze-Omni’s Active Silence BCR is 88.8% in Pre-session trials and 5.0% in In-session trials. Gemini 2.5 Native Audio stays high on both, at 76.3% and 80.0%.
4.12 Content, ≤2.5% BCR
GPT Realtime 2.1 has the highest Agent Interruption content score (4.12), but its BCR is 2.5%, 1.3%, and 1.3% across Pre-session, In-session, and No-explicit.
Best BCR: 8.8%
Only Qwen3.5-Omni exceeds zero on No-explicit Proactive Initiation. VITA-1.5 and DuplexCascade have the lowest latency (10.05 s) but content scores of 0.48 and 0.49, and 0.0% BCR.
Each box is one trial. The profile or instruction sits above the user’s turn, and the three system responses sit together underneath.